
What changed when the requests started failing?
Search retained container logs and compare the first bad request with Docker health, restart, OOM, and resource events from the same window.
Tracebag keeps its logs, runtime counters, Docker state, stack snapshots, and traces in one incident timeline. It runs on your Docker host and stores the evidence there.
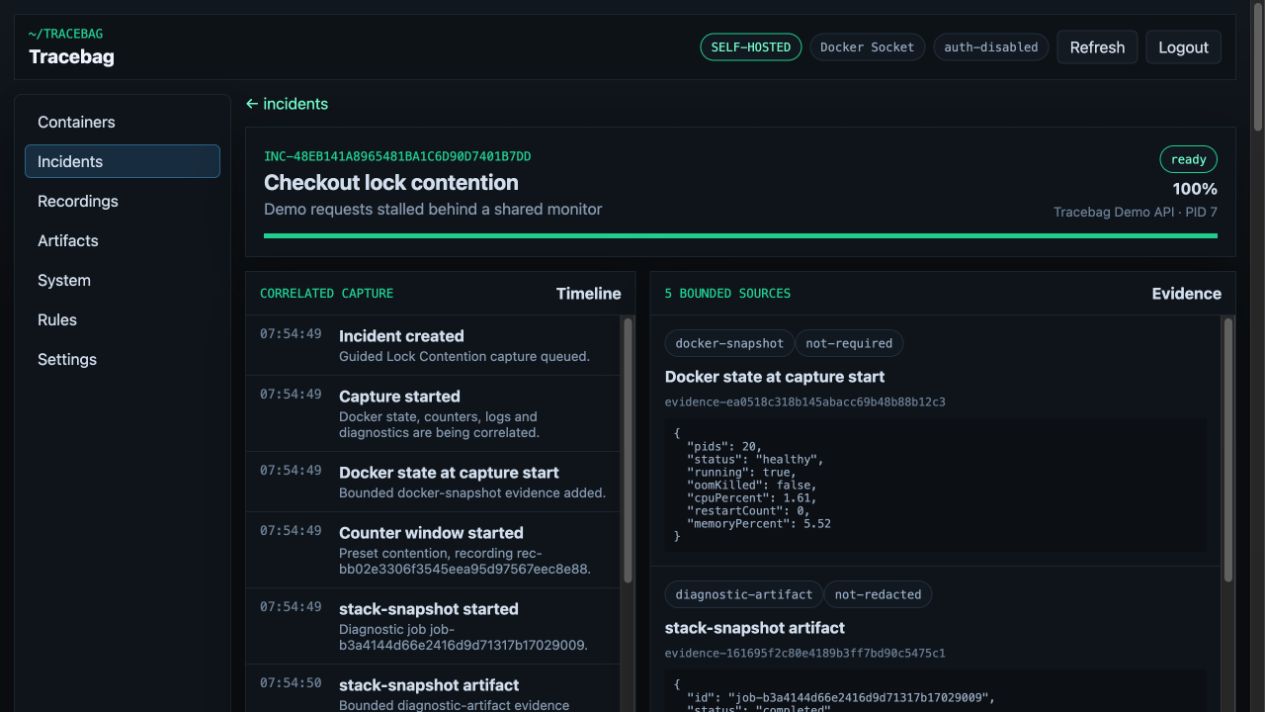
Tracebag is not another general-purpose dashboard. It is a place to investigate one difficult failure and retain enough evidence to explain it later.
Search retained container logs and compare the first bad request with Docker health, restart, OOM, and resource events from the same window.
Watch or record CPU, allocation, GC, ThreadPool, contention, and memory counters without attaching an interactive shell to the workload.
Capture a bounded stack snapshot, EventPipe trace, or dump and keep it with the logs, notes, and exact time range that explain why it was taken.
The demo API can reproduce that exact situation with a bounded lock-contention workload. Tracebag records the counter window, captures stacks and a threading trace, and links the useful findings back to the original evidence.
Nothing in the demo is a mock screenshot or a scripted result. It runs the same images and diagnostic runners used for another opted-in .NET container.
Follow the ten-minute investigation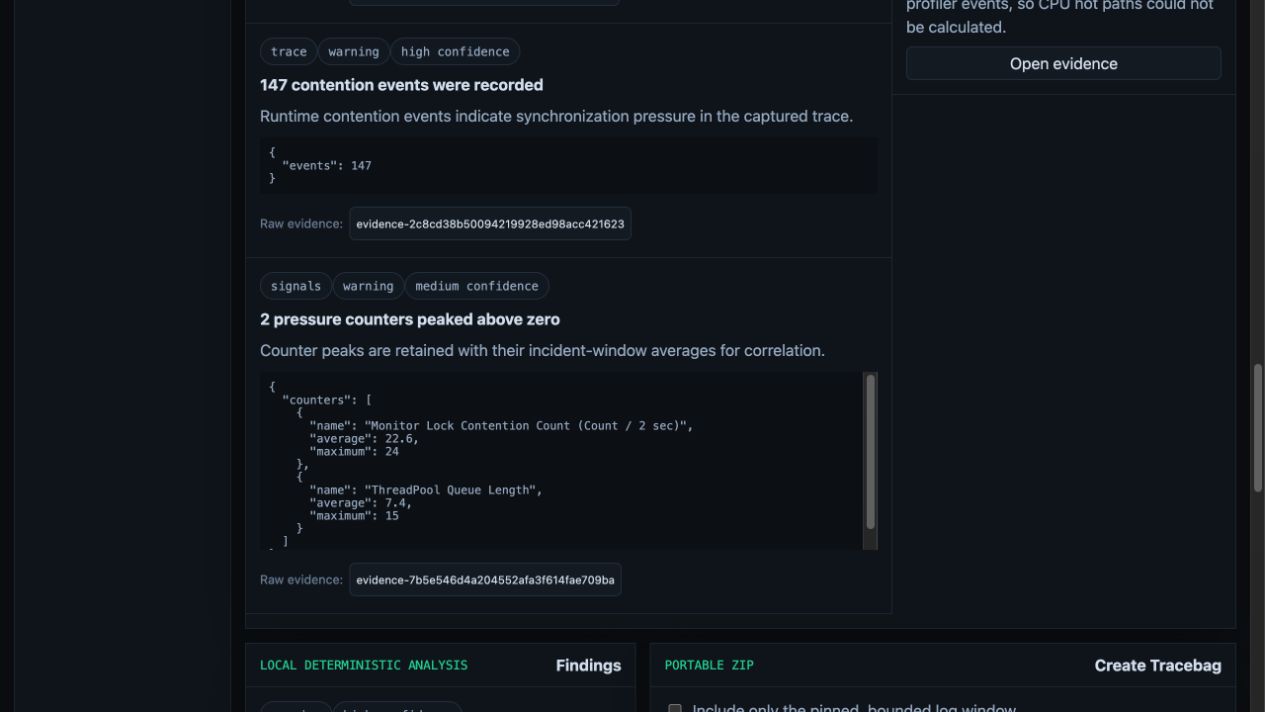
Tracebag uses Docker access to inspect opted-in workloads and launch temporary diagnostic runners. It should run only on a host you control, bound to localhost or protected by a trusted HTTPS proxy.
Read the complete security modelGenerate CPU pressure, allocations, contention, slow requests, downstream failures, or ThreadPool starvation, then investigate the result in Tracebag.